Learn a shared representation space.
Large-scale paired data across modalities, tasks, and domains establish broad coverage in a shared embedding space.
WeChat Vision · Tencent
WeChat Multi-Modal Embedding
WeChat Vision, Tencent Inc.
Universal representations for text, images, videos, visual documents, and mixed inputs. Built for multimodal understanding, retrieval, recommendation, and beyond.
Different inputs. A shared representation.
01 / Method overview
Two-stage training turns a native multimodal foundation into general-purpose embeddings.
Read the methodologyLarge-scale paired data across modalities, tasks, and domains establish broad coverage in a shared embedding space.
Semantic IDs guide resampling to reduce overrepresented patterns and improve semantic balance. Hard negatives further strengthen fine-grained discrimination.
For the same query and candidate samples, the 2B and 4B students learn to match the 9B teacher’s similarity distribution.
02 / Applications


WeMM-Embedding powers search and recommendation at scale across WeChat Channels, Official Accounts, Moments, and e-commerce services. It delivers consistent gains across 14 online A/B tests.
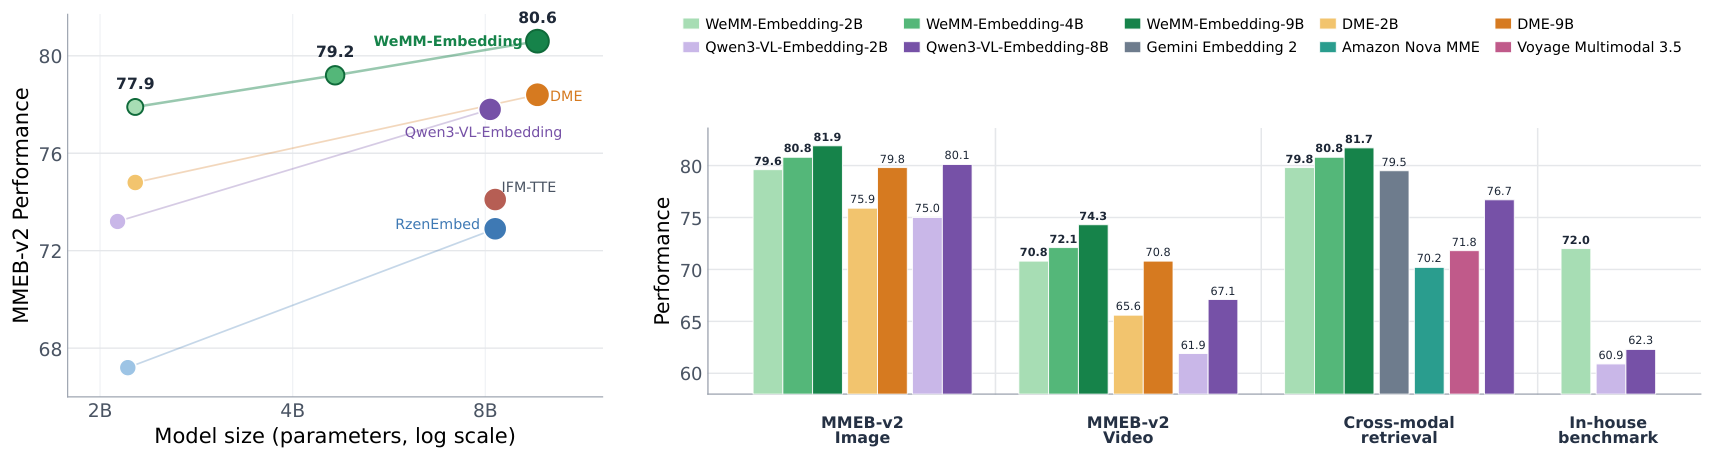
03 / Benchmarks
Results across image, video, visual-document and cross-modal retrieval, alongside in-house evaluations.
04 / Selected benchmark cases
Six real retrieval examples from WeMM-Embedding-9B. Inspect the correct Top-1 match alongside the next two candidates.
Loading benchmark examples…
Benchmark media is shown in limited form for research and evaluation illustration. Copyright remains with the respective owners. Media credits ↗
05 / Open models
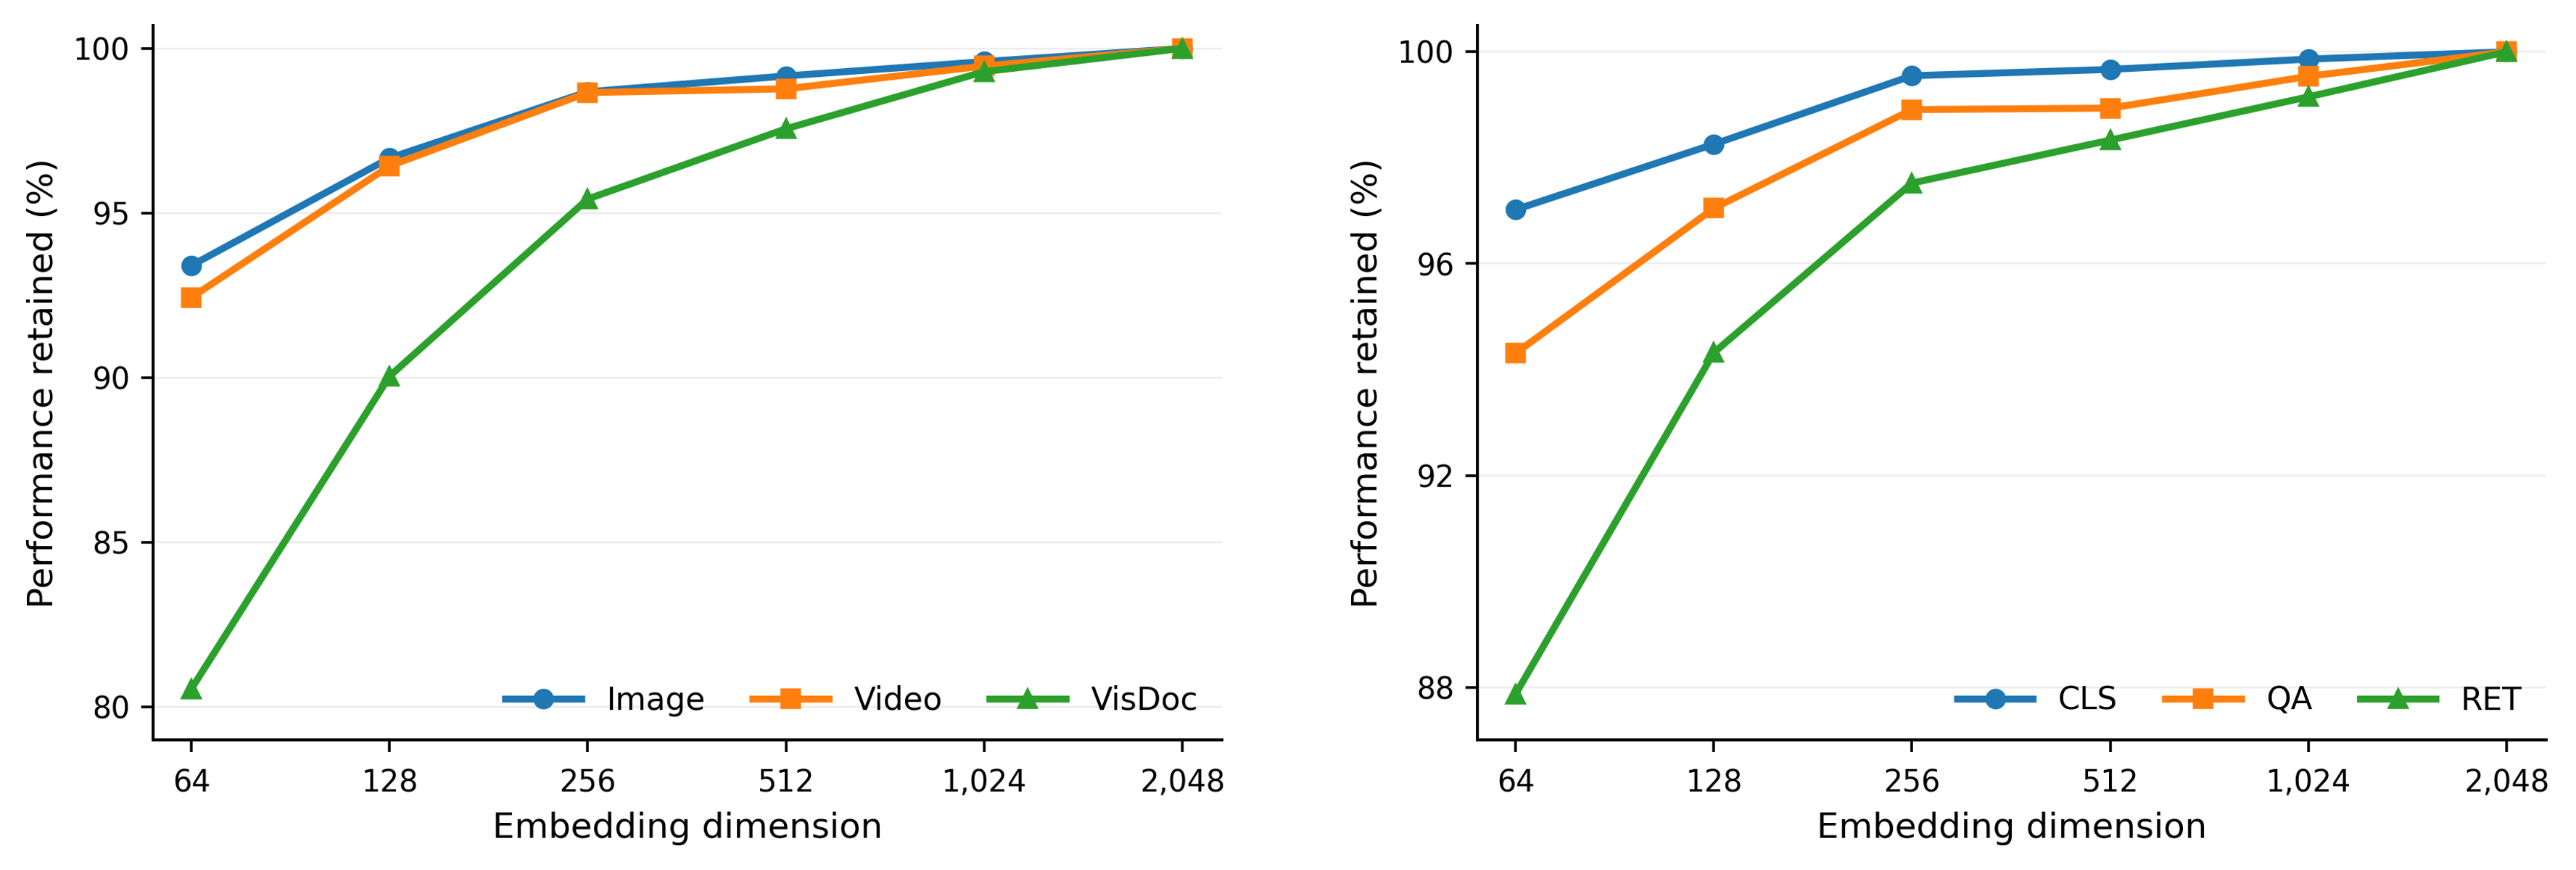
All three models support text, images, video, visual documents, and mixed inputs, with flexible embedding dimensions.
WeMM-Embedding-2B · MRL
One model. Multiple embedding dimensions.
Choose the representation size for your application.
WeMM-Embedding-2B · MMEB-v2
Relative to the full 2,048-dimensional representation.
For 1 million vectors, FP16, decimal GB. Excludes index overhead, metadata, and model weights. Retention values apply to image/video tasks, not visual documents.